Join the Snorkel AI Reading Group, a recurring forum to explore the latest frontier developments in AI while building meaningful connections within the community.
LLMs now beat the human average on standardized medical exams, but a right answer doesn't mean a model reasoned its way there correctly: It might have latched onto an extreme lab value, stray detail, or piece of context a physician would immediately discount, and still landed on the correct choice by accident.
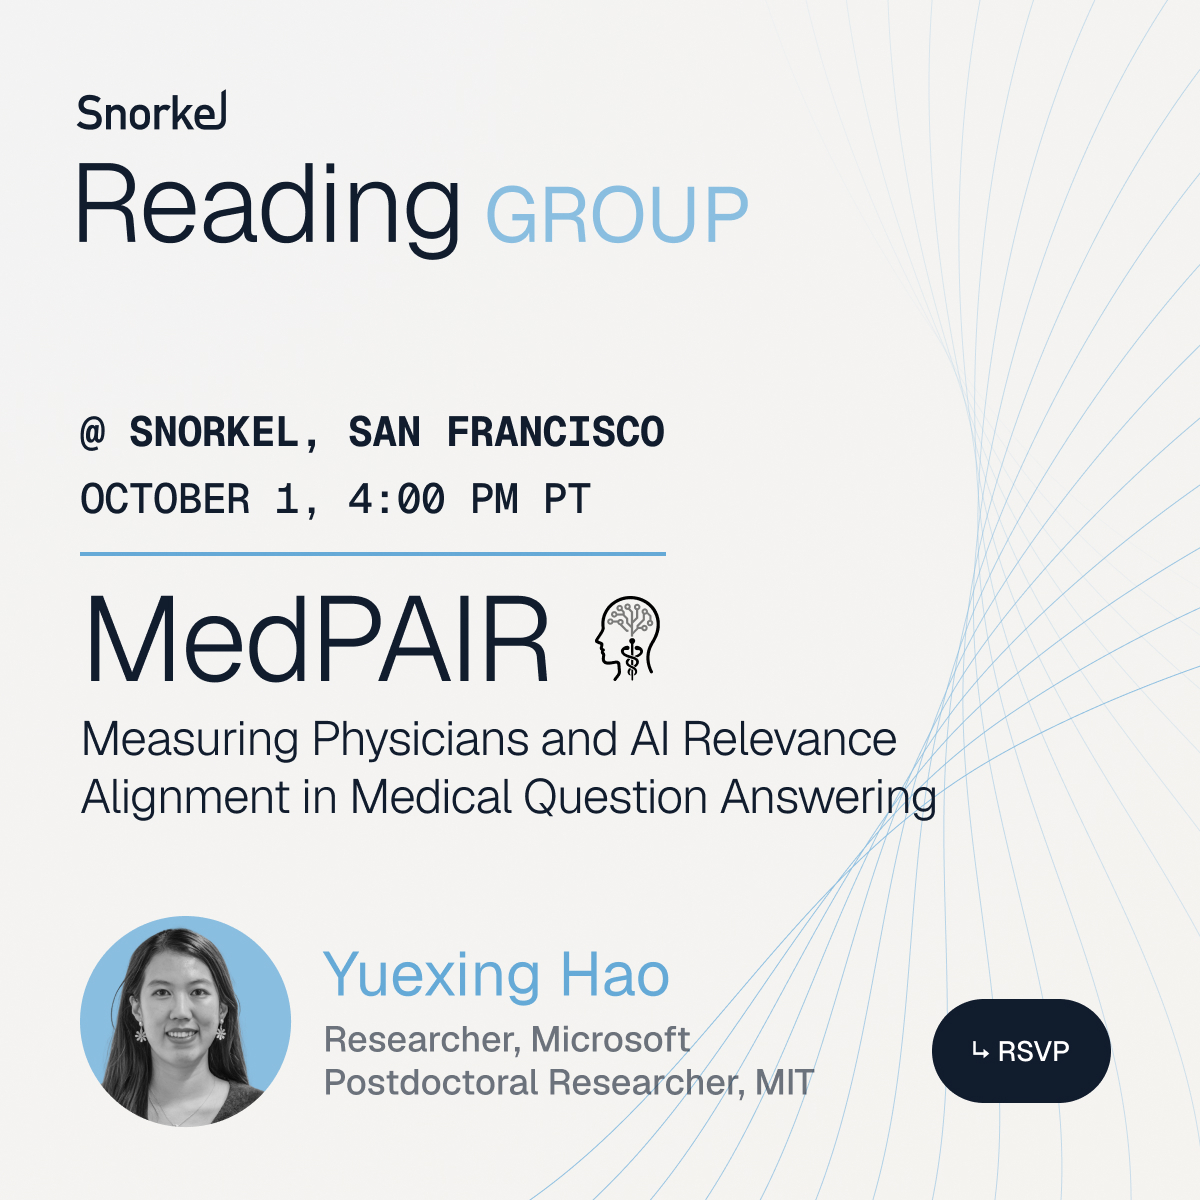
In this session, Yuexing Hao (Microsoft, MIT EECS) will present her work that introduces MedPAIR: Medical Dataset Comparing Physicians and AI Relevance Estimation and Question Answering to catch exactly that gap.
Among other things, you'll learn:
-
Why a model can answer a medical question correctly while relying on completely different - and sometimes spurious - information than a physician would, and why accuracy alone can't catch it.
-
How MedPAIR's sentence-level annotation process surfaces exactly where physicians and LLMs part ways on what counts as clinically relevant.
-
Why models often overweight superficial signals, like an unusually extreme test result, while missing subtler cues that trainees flagged as decisive.
-
Across four medical QA benchmarks, how stripping out the context physicians deemed irrelevant lifted LLM accuracy, which in some cases was enough to beat the physicians' own average.
Agenda:4 pm - doors open4:30 pm - talk begins5:30 pm - research discussion and networking
🧋🧋🧋 Boba tea and other refreshments will be provided ! 🧋🧋🧋
This work appeared as an Oral Presentation in the NeurIPS 2025 Workshop on Socially Responsible and Trustworthy Foundation Models. arXiv preprint available here.
Yuexing Hao is a Researcher at Microsoft and Postdoctoral Associate at MIT EECS Healthy ML Group. She received her PhD in Human-Centered Design from Cornell University.