What does it take for AI systems to truly understand code and what happens when software is no longer designed only for humans, but for AI agents too?
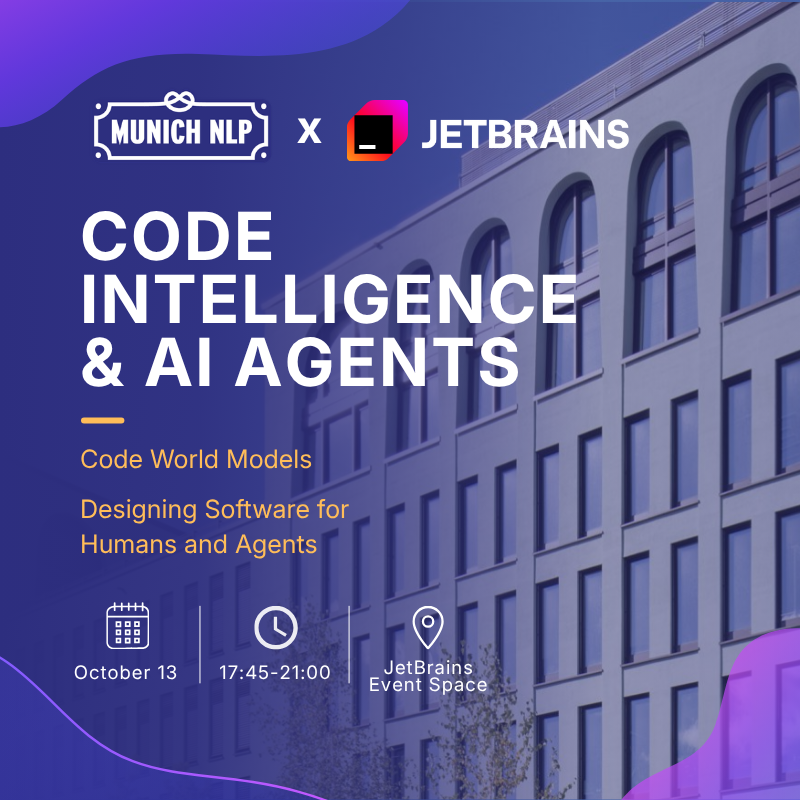
Join Munich🥨NLP and JetBrains for an evening exploring Code Intelligence and AI Agents, bringing together research and industry perspectives on how LLMs understand program behavior and how humans and coding agents can collaborate on software development.
Talk 1: Code World ModelsTobias Lindenbauer · JetBrains Research
Talk 2: Designing Software for Humans and AgentsArtem Kislovskiy · Artefact
Two talks, pizza, drinks & snacks, and plenty of time to connect with Munich’s NLP, AI, and developer community.
📅 Agenda
17:45 | Doors open
18:20 | Pizza arrives 🍕
18:50 | Welcome & IntroJetBrains × Munich🥨NLP
19:00 | Talk 1: “Code World Models”Speaker: Tobias Lindenbauer · JetBrains Research
Abstract
Modern LLMs perform well at generating code that solves a given task, but they may introduce regressions elsewhere in the codebase, or simply write code with poor runtime or memory performance.
This has led researchers to investigate how well LLMs model program behavior internally: Can they tell whether a test passes or fails without running it? Do they have a feel for which parts of the code to target to robustly optimize runtime or memory?
In this talk, Tobias will outline the emerging Code World Models research direction and share early findings from an ongoing project at JetBrains Research.
About the Speaker
Tobias Lindenbauer is a Research Engineer at JetBrains Research working on Code World Models for improved LLM code understanding.
Previously, he worked on context management, LLM routing, memory systems, and benchmarks, resulting in publications at DL4C@NeurIPS and REALM@ACL.
19:40–19:50 | Short break
19:50 | Talk 2: “Designing Software for Humans and Agents”Speaker: Artem Kislovskiy · Artefact
Abstract
One coding agent writes; another challenges.
In this live demo, Claude Code and Codex share a split terminal in an actor–critic loop: the actor implements changes, while the critic reviews them, questions assumptions, and runs checks. Feedback drives the actor’s next revision, and the critic checks again.
We’ll explore how clear responsibilities, inspectable state, and verifiable actions support this collaboration—with the human deciding who acts and who critiques.
About the Speaker
Artem Kislovskiy is a Senior Software Engineer at Artefact in Lausanne, building reliable, Swiss-made software.
20:30 | Networking, drinks & snacks
🎟️ Registration
Registration is free but subject to host approval due to limited capacity. If your plans change, please cancel your registration so we can offer the spot to someone else.