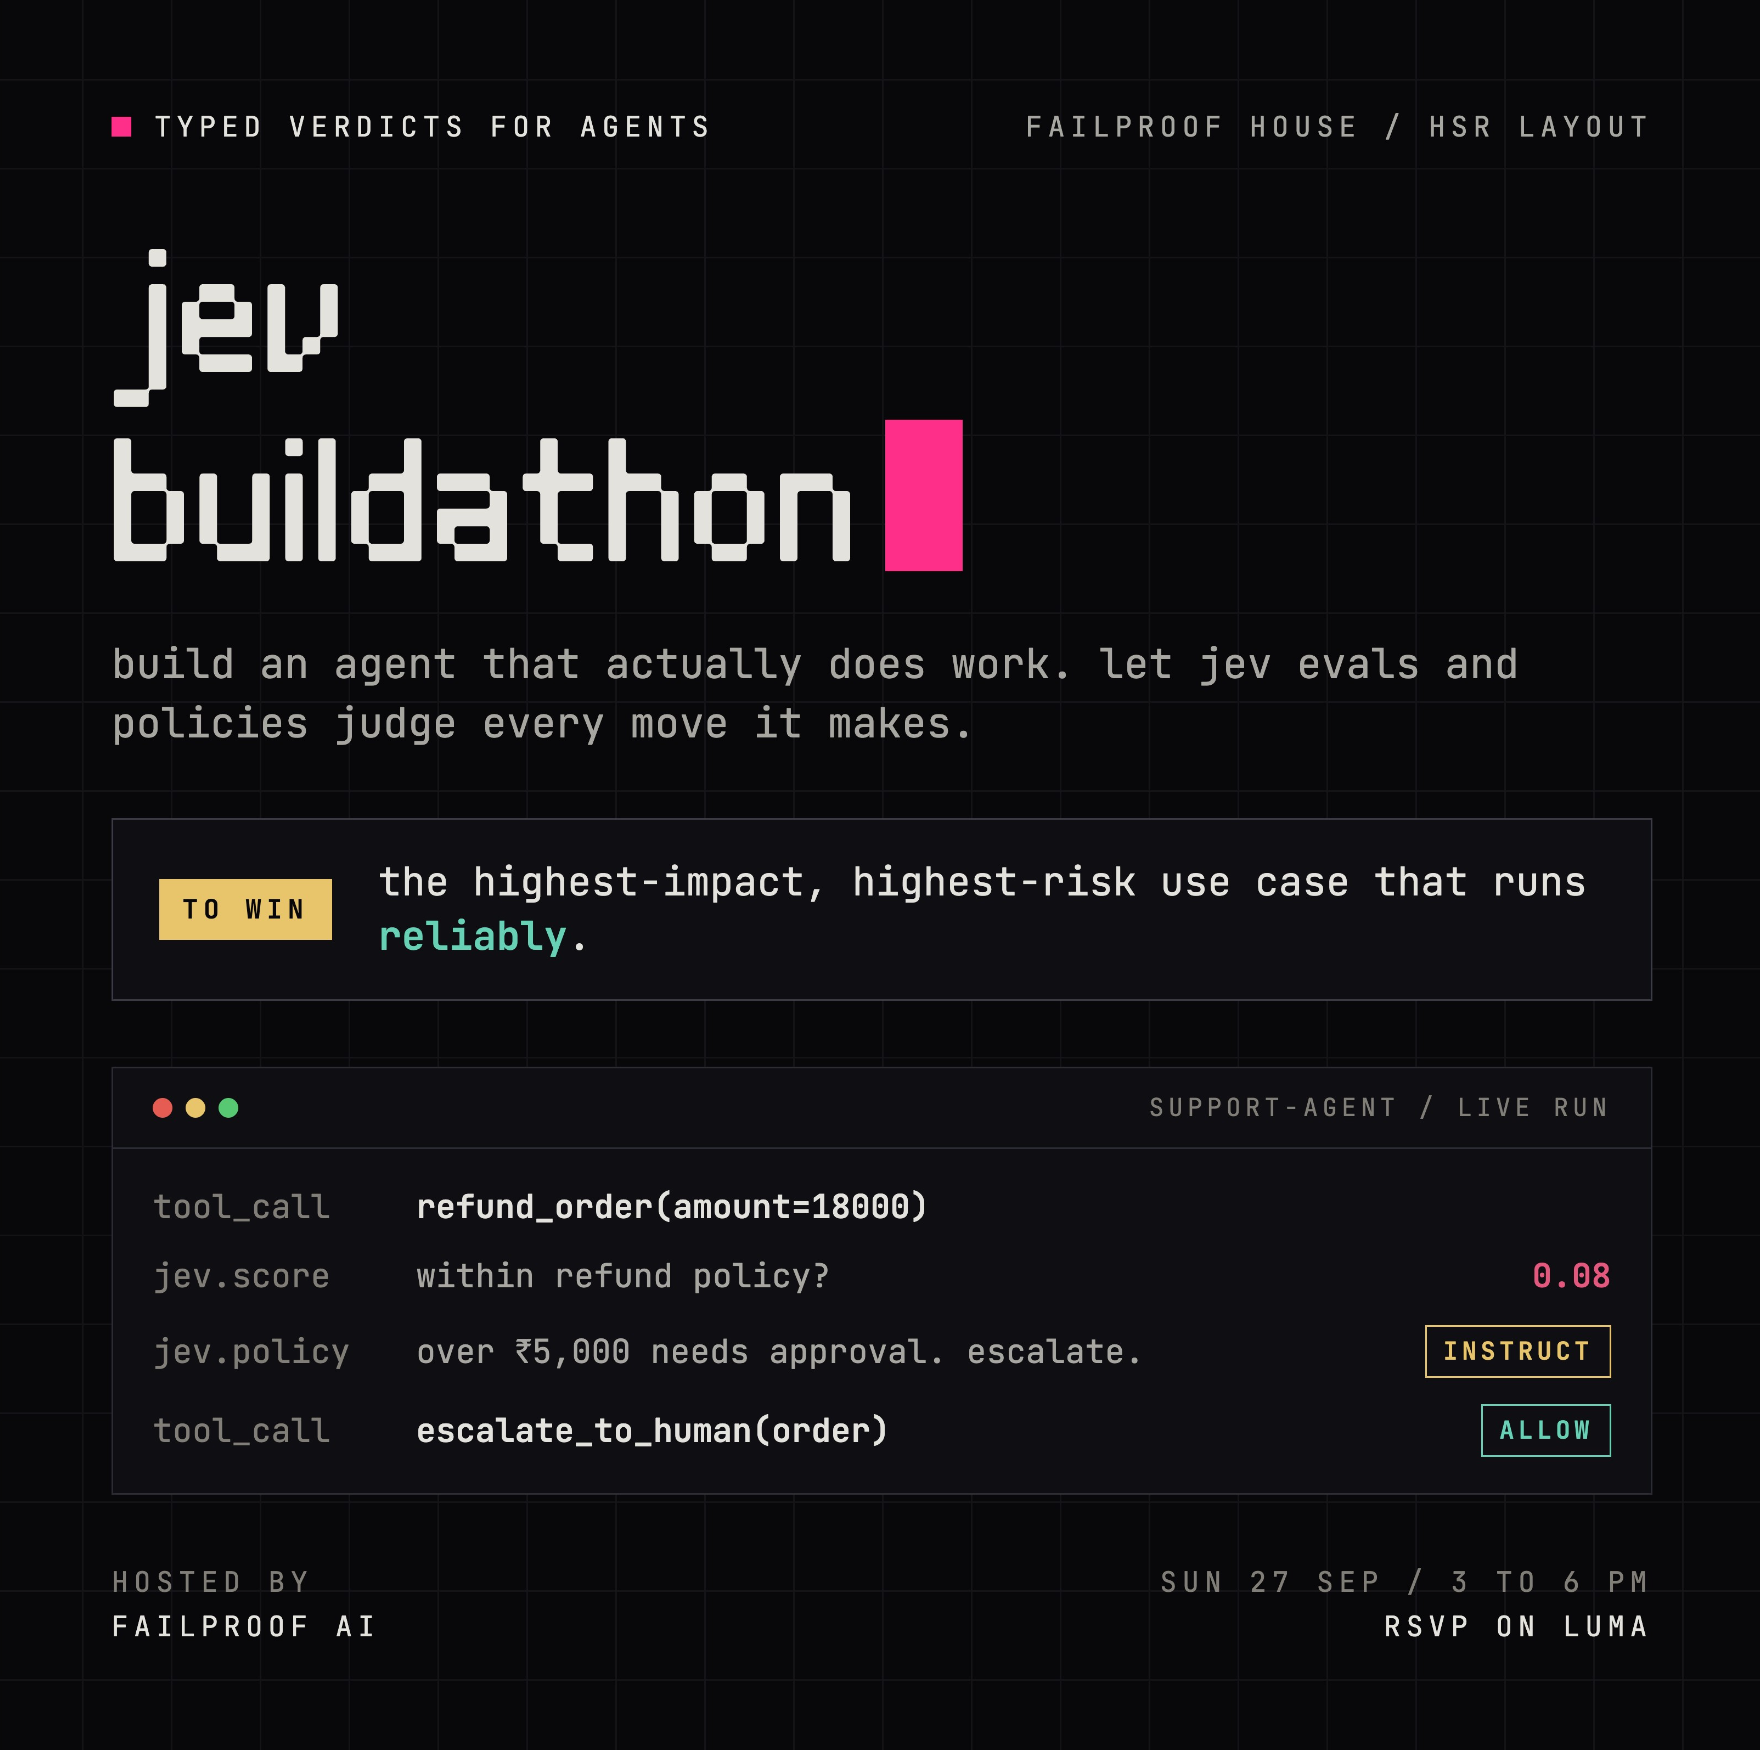
Jev from TypeSafe AI returns typed verdicts (choices, scores, yes/no) instead of text. That makes it a sharp, cheap judge for an agent while it runs, not after. Score every action, check it against a policy, and decide on the spot whether the agent proceeds, stops, or gets told what to do instead.
The brief
-
Build an agent that actually does work. Support, payments, ops, coding, sales, anything where a wrong action costs something.
-
Write Jev evals and policies for it.
-
Demo it. Show us a run where a Jev verdict caught a bad action and steered the agent to the right one.
How the winner is pickedThe highest-impact, highest-risk use case that runs reliably wins.
Anyone can build a safe agent that summarizes docs. We want the agent you'd be nervous to ship, made trustworthy by Jev. We'll look at:
-
Stakes. How much damage could this agent do if it went wrong?
-
Reliability. Does it hold up across runs, not just the one you rehearsed?
-
The save. A clear moment where a Jev verdict changed what the agent did.
Ambitious and shaky loses to ambitious and solid.
Schedule3:00 pm Kickoff: Jev evals and policies walkthrough3:20 pm Build5:15 pm Demos5:50 pm Winner + wrap
BringYour laptop, your charger, and an agent idea (or a half-built one). Solo or teams of up to [N].
Before you comeGet Jev access via OpenRouter or the early access waitlist at typesafe.ai. Build time is tight, so sort this out before Sunday. No access yet? Come anyway, we'll pair you up. We'll have Failproof set up so your Jev policies can run on live agent tool calls.About Failproof AIFailproof is your agent's oversight layer, steering it towards success. It traces your agents, finds failure patterns over time and sets up rules to prevent them from happening again. We just launched Jev evals and policies on Failproof to unlock better reliability at least cost and latency.
Came to Jev CoLearn? This is the sequel. Didn't? You'll catch up in the first 15 minutes.