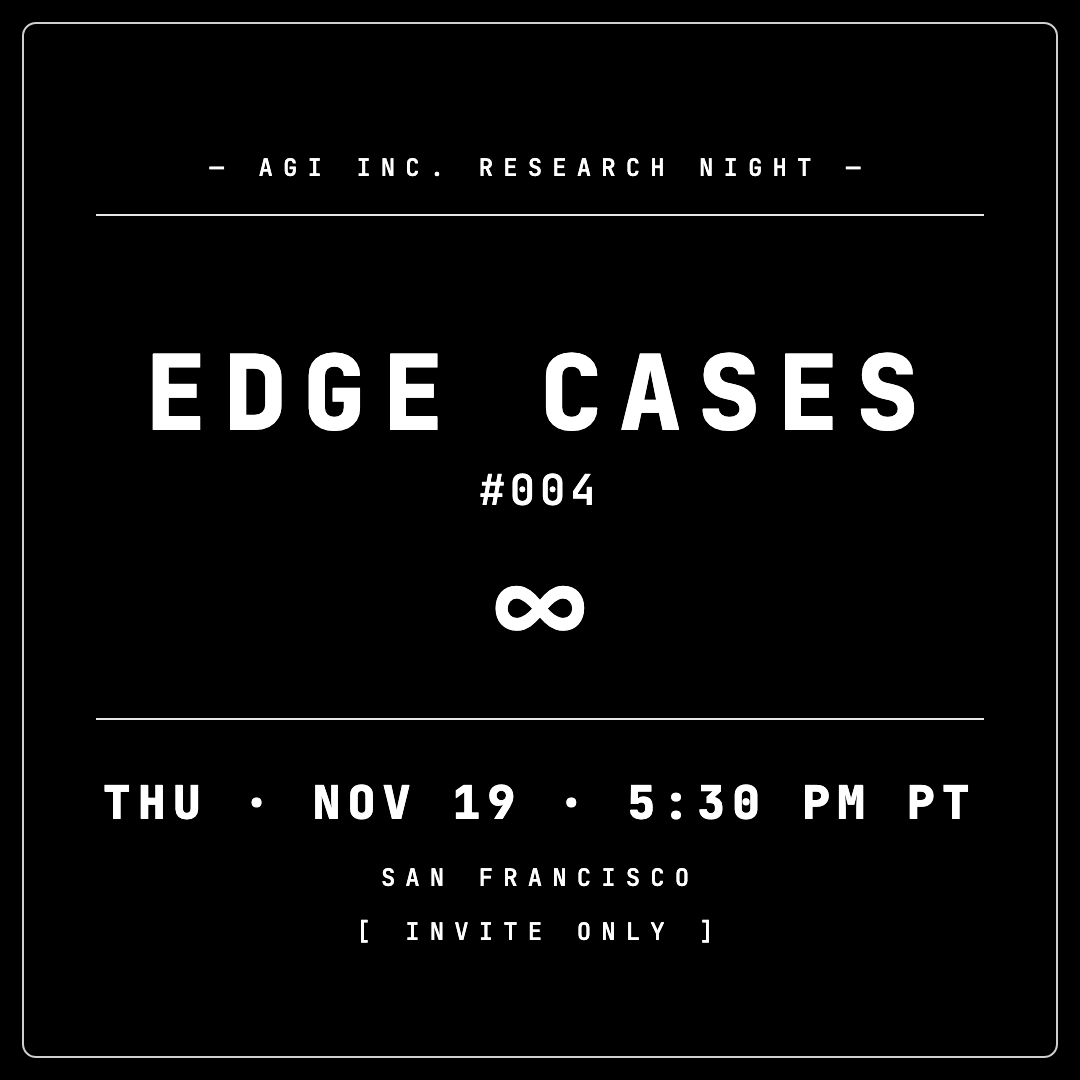
Edge Cases is AGI, Inc.'s invite-only research night on what it takes to run real intelligence on-device.
Speaker
Coleman Hooper, postdoctoral scholar at UC Berkeley (BAIR and SLICE Lab). PhD at Berkeley, advised by Kurt Keutzer and Sophia Shao. Works on AI systems, efficient LLM inference and hardware-software co-design for ML. LinkedIn
Talk
Efficient edge inference through parallel and looped generation
In the cloud, LLM inference batches across many users. On a device there is one user, so decoding runs at batch size one and most of the hardware's parallel compute goes unused. Coleman will cover two ways around this. Diffusion language models refine several tokens in parallel, and his work trains them to need fewer refinement steps. Looped transformers pass each token through the model multiple times, and self-speculative decoding uses the earlier loops for drafting and the later loops for verification. The talk ends with recent work that combines the two for speedups above 10x.
Papers: MLSys 2026 · Springer chapter · one more on arXiv by the talk
Details
-
Thursday, November 19, 5:30 PM
-
Our founders' house in San Francisco. Exact address shared on approval.
-
30 to 40 minute talk, off-the-record Q&A, then dinner with the group
-
For AI researchers, PhD students and research engineers
-
Seats are limited and registration is approval-based
More about the series: theagi.company/edge-cases
Want to present your on-device research at a future Edge Cases? Apply here
Full text on Luma
.